Prefix sums and difference arrays
frequent
What are prefix sums and difference arrays?
Prefix sums and difference arrays both maintain an auxiliary array to describe the state of the current array. They are similar, but their purposes and implementation methods are different.
Prefix sums: A prefix sum array stores the running total up to each position, so any range sum becomes a single subtraction. Generating it takes preprocessing, and each query then takes . In 2D, we will need the inclusion-exclusion principle as well.
Difference arrays: A difference array can achieve uniform range updates in time complexity per operation. After the difference array is generated, the original array can be restored by performing a prefix sum operation on it.
Prefix Sums
The recurrence for prefix sums looks something like this:
s[i]=s[i-1]+v[i];Here array s is the prefix sum array, and v is the original array.
So for an array of length n, we can generate the prefix sum array s with the following code (arrays are 1-indexed, and n is at most 1000):
int v[1001];
int s[1001];
memset(v,0,sizeof(v)); // initialize
memset(s,0,sizeof(s));
int n;
cin>>n;
for(int i=1;i<=n;i++){
    cin>>v[i]; // input
}
for(int i=1;i<=n;i++){
    s[i]=s[i-1]+v[i]; // generate
}
Just like that, we get the prefix sum array s.
As mentioned earlier, the prefix sum array can quickly find a range sum using the following method:
int total=s[j]-s[i-1];Here, total is the range sum from v[i] to v[j]. s[j] covers everything up to j, and s[i-1] is the part before i, so subtracting leaves exactly the range. Each query takes .
Difference Arrays
Difference arrays are similar to prefix sums; both process arrays.
As usual, let's jump straight to the recurrence:
d[i]=v[i]-v[i-1];d is the difference array, and v is the original array.
Similarly:
int v[1001];
int d[1002]; // size n+2, because an update below touches d[j+1]
memset(v,0,sizeof(v)); // initialize
memset(d,0,sizeof(d));
int n;
cin>>n;
for(int i=1;i<=n;i++){
    cin>>v[i]; // input
}
for(int i=1;i<=n;i++){
    d[i]=v[i]-v[i-1]; // generate
}
Now we have the difference array. And just like we described earlier, the whole point of creating a difference array is to uniformly update all numbers within a range.
Once we have the difference array, how do we restore the original array? We use the exact same method as the prefix sum array generation:
for(int i=1;i<=n;i++){
    v[i]=v[i-1]+d[i];
}
Here is how it works:
Index:                                  0, 1, 2, 3, 4, 5
Original array:                         0, 1, 2, 3, 4, 5
Difference array:                       0, 1, 1, 1, 1, 1
Prefix sum op on the difference array:  0, 1, 2, 3, 4, 5
How do we implement updates?
Now our goal is to add 1 to each element from the i-th to the j-th position in array v. Using a regular loop, the complexity is .
for(int t=i;t<=j;t++){
    v[t]++;
}
But when the gap between i and j is large, you'll get a TLE (Time Limit Exceeded).
However, if we modify the difference array directly, the story is completely different. For example, adding 1 to each element from position 1 to position 3:
Index: 0, 1, 2, 3, 4, 5
Orig:  0, 1, 2, 3, 4, 5
Diff:  0, 1, 1, 1, 1, 1
Mod:   0, 2, 1, 1, 0, 1
Sum:   0, 2, 3, 4, 4, 5
As you can see, we only modified two values, yet we updated the entire range. The method is now crystal clear:
d[i]+=c;
d[j+1]-=c;
This adds c to every value between i and j.
Note that difference arrays work best when all the updates come first and the array is read afterwards. We do all the updates, restore the array once, and then answer the queries.
2D Prefix Sums
Sometimes, a 1D prefix sum just doesn't cut it, so we can introduce 2D prefix sums.
The principle is similar. Here is the generation code. In C++, declare these arrays globally: a 1001 by 1001 int array takes about 4 MB, and local arrays of this size can overflow the stack. Global arrays also start out filled with 0.
int v[1001][1001];
int s[1001][1001]; // 2D prefix sum array

int main(){
    int n;
    cin>>n;
    for(int i=1;i<=n;i++){
        for(int j=1;j<=n;j++){
            cin>>v[i][j];
        }
    }
    for(int i=1;i<=n;i++){
        for(int j=1;j<=n;j++){
            s[i][j]=s[i-1][j]+s[i][j-1]-s[i-1][j-1]+v[i][j];
        }
    }
}
For the sum query, we also need the help of the inclusion-exclusion principle. To sum the rectangle with top-left corner (x1,y1) and bottom-right corner (x2,y2), subtract the part above it and the part to its left, then add back the corner that was subtracted twice:
int total=s[x2][y2]-s[x1-1][y2]-s[x2][y1-1]+s[x1-1][y1-1];Example Problem 1: J5/S2 Beams of Light
Theory is easier to understand with practice. Let's look at the problem first:
Beams of Light2026 · J5 · Original problem · DMOJ
Along one wall of a parking garage there are identical parking spots numbered from to . A collection of lights illuminates the parking garage. Each light shines on some number of adjacent parking spots.
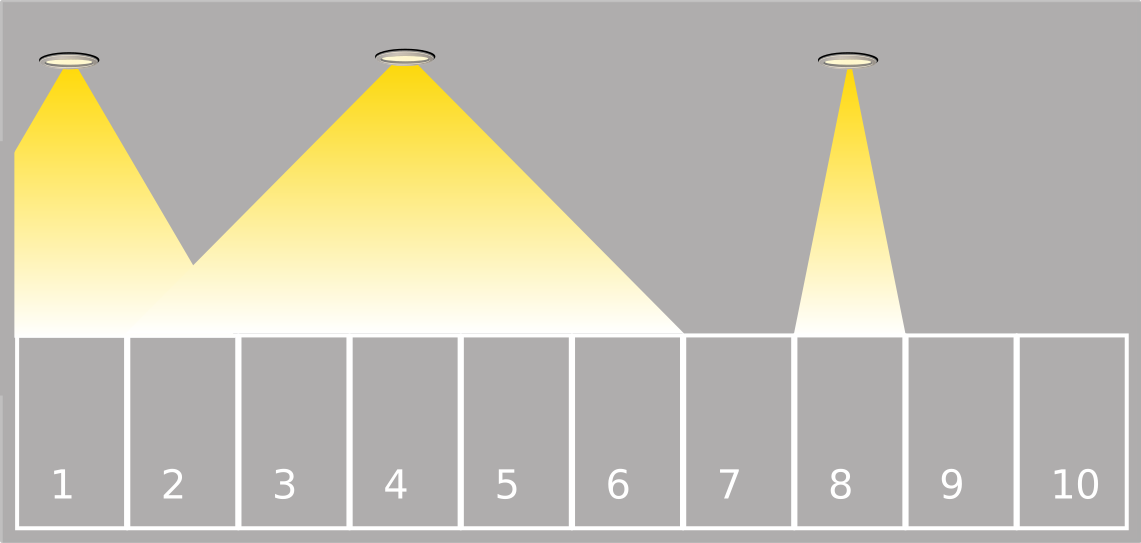
You will be questioned about the parking spots. For each parking spot you are questioned about, your job is to determine whether or not it is illuminated by at least one light.
The first line of input contains a positive integer, , representing the number of parking spots. The second line contains a non-negative integer, , representing the number of lights. The third line contains a positive integer, , representing the number of parking spots you will be questioned about.
The next lines provide information about the lights. Line will contain two integers, and , separated by a single space. The first integer, , represents the number of the parking spot above which a light is hung. The second integer, , represents the spread of the light's beam. Light shines on the parking spot that is directly below it. It also shines on the parking spots located on either side, unless there are fewer than spots on a side, in which case all the spots on that side will be illuminated. There could be more than one light directly above a parking spot.
The next lines of input each contain a positive integer between and inclusive, representing the number of the parking spot you are questioned about.
The following table shows how the available marks are distributed:
| Marks | Number of Spots | Number of Lights | Number of Questions |
|---|---|---|---|
There will be one line of output for each of the parking spots you are questioned about.
On each of these lines, output Y if the corresponding parking spot is illuminated by at least one light, or N if the corresponding parking spot is not illuminated by any light.
10
3
4
8 0
1 1
4 2
4
10
7
1
Output for Sample Input
Y
N
N
Y
Explanation of Output for Sample Input
The input describes the following picture of the parking garage.
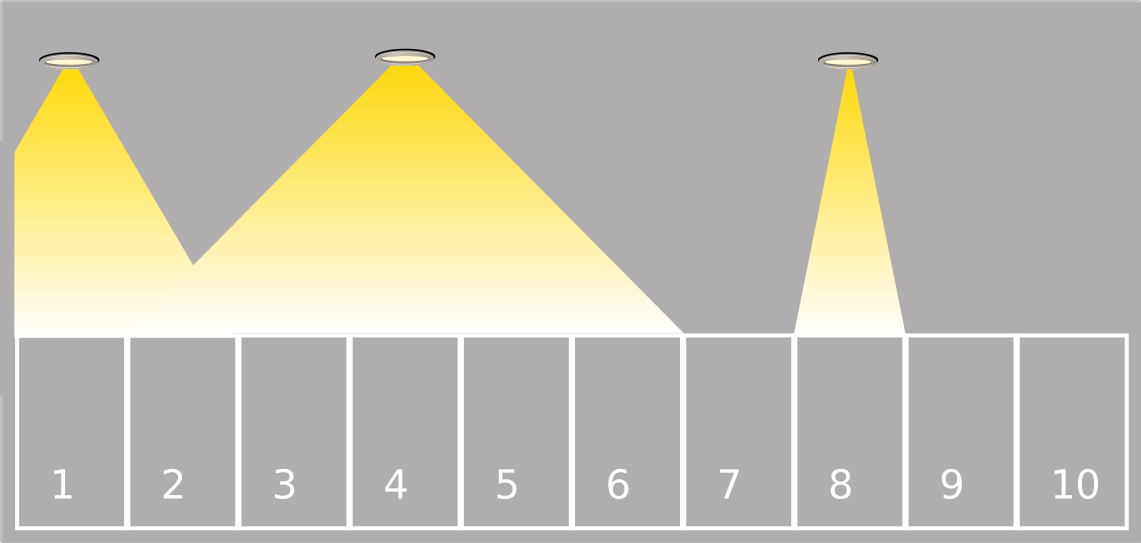
Parking spots and are illuminated by at least one light.
Parking spots and are not illuminated by any light.
In other words:
Each light at position sp with width w illuminates the parking spaces from sp-w to sp+w (cut off at space 1 and at space nos), and we need to answer nt queries on whether a specific parking space is illuminated.
If we use a loop to mark every space of every beam, one beam can touch up to 500000 spaces, and we might have to mark 500000 times.
In the worst-case scenario, we would need to execute loop iterations, which is a guaranteed TLE.
But if we use a difference array, the complexity of each mark is .
In the worst case, the total operations are roughly (marking) + 500000 (generating the corresponding original array) + 500000 (queries).
This way, it won't time out.
Two details to watch:
- Clamp the start and end of each beam to the range 1 to
nos. Thensub[e+1]is at mostsub[nos+1], which is whysubhas one extra slot. - With 500000 queries, input and output speed matters. In C++, turn off I/O syncing and print
'\n'instead ofendl, sinceendlflushes the output on every line. In Python, read all the input at once and print once at the end.
Here's the code:
#include<bits/stdc++.h>
using namespace std;
int mp[500001];
int sub[500002];
int main(){
    ios::sync_with_stdio(false);
    cin.tie(nullptr);
    int nos,nol,nt;
    cin>>nos>>nol>>nt; // number of parking spaces, number of lights, number of queries
    for(int i=1;i<=nol;i++){
        int sp,w;
        cin>>sp>>w;
        int s=max(1,sp-w); // start, clamped to 1
        int e=min(nos,sp+w); // end, clamped to nos
        sub[s]++; // mark the start
        sub[e+1]--; // mark the end
    }
    for(int i=1;i<=nos;i++){
        mp[i]=mp[i-1]+sub[i]; // generate the corresponding array
    }
    for(int i=1;i<=nt;i++){
        int p; // query
        cin>>p;
        if(mp[p]==0){
            cout<<"N\n";
        }else{
            cout<<"Y\n";
        }
    }
}
Example Problem 2: J5/S2 Modern Art
This one is similar, but it isn't a textbook template problem like Beams of Light, and it's actually simpler.
Modern Art2021 · J5 · Original problem · DMOJ
A new and upcoming artist has a unique way to create checkered patterns. The idea is to use an -by- canvas which is initially entirely black. Then the artist repeatedly chooses a row or column and runs their magic brush along the row or column. The brush changes the colour of each cell in the row or column from black to gold or gold to black.
Given the artist’s choices, your job is to determine how much gold appears in the pattern determined by these choices.
The first line of input will be a positive integer . The second line of input will be a positive integer . The third line of input will be a positive integer . The remaining input will be lines giving the choices made by the artist. Each of these lines will either be R followed by a single space and then an integer which is a row number, or C followed by a single space and then an integer which is a column number. Rows are numbered top down from to . Columns are numbered left to right from to .
The following table shows how the available 15 marks are distributed.
| 1 mark | only one cell, and up to 100 choices by the artist | |||
| 4 marks | only one row, and up to 100 choices by the artist | |||
| 5 marks | up to 100 rows, up to 100 columns, and up to 100 choices by the artist | |||
| 5 marks | up to 5000000 cells, and up to 1000000 choices by the artist | |||
Output one non-negative integer which is equal to the number of cells that are gold in the pattern determined by the artist’s choices.
3
3
2
R 1
C 1
Output for Sample Input 1
4
Explanation of Output for Sample Input 1
After running the brush along the first row, the canvas looks like this:
GGG
BBB
BBB
Then after running the brush along the first column, four cells are gold in the final pattern determined by the artist’s choices:
BGG
GBB
GBB4
5
7
R 3
C 1
C 2
R 2
R 2
C 1
R 4Output for Sample Input 2
10
Explanation of Output for Sample Input 2
Ten cells are gold in the final pattern determined by the artist’s choices:
BGBBB
BGBBB
GBGGG
GBGGG
In other words, the canvas has x rows and y columns. At the very beginning, all cells are black (B), and we need to count the number of gold cells (G) after the instructions. Each instruction flips every cell in one row (R idx) or one column (C idx).
Every cell is initially marked with 0 paint operations.
From this, we get a traditional brute-force simulation idea.
First, we define a grid and initialize every cell to black (for now, a small grid of at most 1000 by 1000):
char mp[1001][1001];
for(int i=1;i<=1000;i++){
    for(int j=1;j<=1000;j++){
        mp[i][j]='B';
    }
}
Then read in the instructions.
For example: R 1 flips row 1, so idx = 1.
We just run a loop over that row:
for(int j=1;j<=y;j++){
    if(mp[idx][j]=='B'){
        mp[idx][j]='G';
    }else{
        mp[idx][j]='B';
    }
}
A C idx instruction works the same way, looping i from 1 to x over mp[i][idx].
Just like that, we've marked one instruction.
In the subsequent query phase, we traverse the entire grid to find all cells with the value G:
int ans=0;
for(int i=1;i<=x;i++){
    for(int j=1;j<=y;j++){
        if(mp[i][j]=='G'){
            ans++;
        }
    }
}
cout<<ans;
This works for small canvases, but it doesn't scale.
According to the problem constraints, the canvas can have up to 5000000 rows and 5000000 columns, so in the worst case our grid (mp) would have to be defined as:
char mp[5000001][5000001];That is about 25 TB even at one byte per cell, far beyond any memory limit (MLE, Memory Limit Exceeded), in any language.
Dynamic arrays (vectors in C++, lists in Python) don't solve this. Even if the memory fit, marking the instructions would still be too slow: up to 1000000 instructions, each flipping up to 5000000 cells, is roughly operations in the worst case. That is far beyond the time limit, so it would get a TLE.
So why not borrow the idea behind difference arrays: instead of updating cells one by one, record how many times each row and column is operated on, and work out the cells afterwards.
Initially, the operation count is 0, and the cell is black.
Count: 0 1 2 3 4 5
Color: B G B G B G
Spot the pattern?
That's right, if the total number of operations on a cell is odd, the cell will be gold.
So how do we calculate the number of operations on a single cell?
Take a 2-row by 2-column grid for example.
B B
B B
Now execute operation R1:
G G
B B
All of row 1 has been operated on once.
Now C1:
B G
G B
Cell (1,1) has been operated on twice in total, so cell (1,1) is B.
In other words:
Total operations on a cell = Total operations on its row + Total operations on its column.
Now the approach is clear.
- Count the number of operations for each row and each column.
int r[5000001];
int c[5000001];
// ... inside main:
int x,y,noa;
cin>>x>>y>>noa;
for(int i=1;i<=noa;i++){
    char tp;
    int idx;
    cin>>tp>>idx;
    if(tp=='R'){
        r[idx]++;
    }else{
        c[idx]++;
    }
}-
Traverse the entire grid.
If the total operations on the cell is odd,
ans++.Otherwise, continue.
long long ans=0;
for(int i=1;i<=x;i++){
    for(int j=1;j<=y;j++){
        if((r[i]+c[j])%2==1){
            ans++;
        }
    }
}- Output the answer.
This traversal costs , which is fine for small canvases. If your version of the problem allows x and y up to 5000000, that is far too slow (and the answer can exceed the range of int, so use long long). Python loops are much slower than C++ loops, so in Python this traversal runs out of time on even moderately large canvases.
But only the parity of each row and column matters. Let ro be the number of rows with an odd count, and co the number of columns with an odd count. A cell is gold when its row is odd and its column is even, or the other way around:
Now no grid traversal is needed at all. So, here is the final solution code, which runs in time, where is the number of instructions:
#include<bits/stdc++.h>
using namespace std;
int r[5000001];
int c[5000001];
int main(){
    int x,y;
    cin>>x>>y;
    int noa;
    cin>>noa;
    for(int i=1;i<=noa;i++){
        char tp;
        int idx;
        cin>>tp>>idx;
        if(tp=='R'){
            r[idx]++;
        }else{
            c[idx]++;
        }
    }
    long long ro=0,co=0;
    for(int i=1;i<=x;i++){
        if(r[i]%2==1){
            ro++;
        }
    }
    for(int j=1;j<=y;j++){
        if(c[j]%2==1){
            co++;
        }
    }
    cout<<ro*(y-co)+(x-ro)*co;
}
Partial content translated by Gemini-4-Argon from Chinese.